In an era where digital connectivity is the lifeblood of global commerce and governance, the recent Microsoft outage has emerged as perhaps the most significant technological disruption of the decade. As businesses across continents ground to a halt, the scale of the crisis became evident when major financial institutions, healthcare providers, and government agencies reported widespread system failures. This unprecedented event, triggered by a faulty software update from the cybersecurity firm CrowdStrike, caused millions of Windows machines to enter a perpetual loop of the dreaded Blue Screen of Death (BSOD). The Hindu reports that the situation is so critical that Microsoft has taken the extraordinary step of extending its mail server timeout to 48 hours. This move is designed to ensure that the massive backlog of emails, currently suspended in digital limbo, is not permanently lost as systems struggle to re-establish connectivity. For organizations reliant on real-time communication, the extension serves as a vital safety net, though it underscores the sheer volume of data congestion caused by the sudden paralysis of the global cloud infrastructure. This analysis delves into the technical, economic, and institutional fallout of a world momentarily disconnected from its primary OS environment.
The Genesis of the Global Shutdown: A Technical Post-Mortem
The root cause of this systemic collapse was not a malicious cyberattack, but rather a catastrophic failure in the software deployment pipeline of CrowdStrike, a leading provider of endpoint protection. A routine update to the Falcon sensor—a kernel-level driver designed to protect Windows systems—contained a logic error that caused the operating system to crash immediately upon booting. Because the driver operates with high-level privileges within the Windows kernel, the system had no way to bypass the error, resulting in a worldwide fleet of non-functional hardware. The Hindu’s live tracking of the event highlighted that even the most robust enterprise environments were vulnerable because they shared a common dependency on this single security vendor.
Recovery efforts have proven exceptionally difficult because the fix requires manual intervention on every affected device. Administrators must boot machines into Safe Mode or the Windows Recovery Environment to manually delete the offending driver file. In a world where many servers and workstations are managed remotely or stored in massive data centers, this physical requirement has created a logistical nightmare. Microsoft’s involvement has shifted from merely hosting the environment to actively developing tools that can automate this recovery process via USB or PXE boot, though the rollout of these solutions is hampered by the very outages they seek to repair.
The Specifics of the 48-Hour Mail Timeout Extension
As the outage persisted, one of the most pressing concerns for global corporations became the integrity of their email communications. Under normal operations, Simple Mail Transfer Protocol (SMTP) servers have a defined retry period for undelivered mail. If a recipient’s server is unreachable for a standard duration—typically 24 hours—the sending server may ‘bounce’ the email back to the sender, resulting in lost information and disrupted workflows. By extending this timeout to 48 hours, Microsoft is effectively telling the world’s mail servers to hold onto their outgoing messages for a longer period, betting that the vast majority of affected organizations will have restored their systems within that two-day window.
This extension is particularly crucial for government organizations and legal entities where the timestamp of an email can have significant regulatory implications. The Hindu notes that many Indian government portals and administrative offices faced delays in processing critical applications during the downtime. The extended timeout ensures that these official communications are queued rather than deleted, preventing a secondary crisis of lost records and missed deadlines. However, the move also signals that Microsoft expects the full recovery of the global digital ecosystem to take significantly longer than initially anticipated, as the backlog of unsent data will likely cause significant latency once systems are fully back online.
The Domino Effect on Global Infrastructure and Aviation
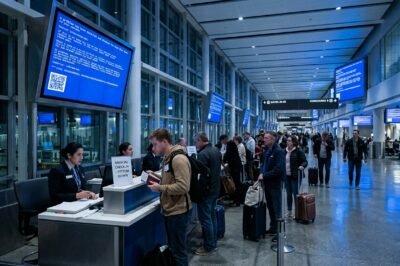
The human impact of the outage was most visible in the world’s airports. From London Heathrow to Delhi’s Indira Gandhi International, flight boards turned black or displayed error messages. Airlines like Indigo and Air India were forced to issue handwritten boarding passes, a scene reminiscent of the pre-digital era. The Hindu reported that thousands of passengers were stranded as automated check-in systems and baggage handling software failed simultaneously. The disruption extended beyond just the logistics of travel; it impacted the safety-critical systems used for flight planning and weather monitoring, leading to thousands of cancellations worldwide.
In the healthcare sector, the consequences were even more dire. Hospitals in the United Kingdom and parts of Europe reported that they were unable to access digital patient records or schedule emergency surgeries. The reliance on centralized cloud systems meant that when the ‘connection’ broke, the ability to provide life-saving care was severely compromised. This has sparked a renewed debate about the necessity of local, offline backups for critical infrastructure. While the cloud offers efficiency and scalability, this outage has demonstrated that it also introduces a single point of failure that can paralyze entire nations.
Financial and Market Implications for Big Tech
The financial markets reacted swiftly to the news of the outage. Microsoft (MSFT) and CrowdStrike (CRWD) saw significant fluctuations in their stock prices as investors began to quantify the potential liability and reputational damage. For CrowdStrike, the incident is an existential threat to its brand as a ‘reliable’ security provider. The Hindu’s business desk observed that the insurance industry is now bracing for a wave of business interruption claims that could reach billions of dollars. The complexity of these claims is heightened by the fact that the outage was caused by a software vendor rather than a direct cyberattack, leading to potential disputes over policy coverage and subrogation.
Furthermore, the outage has highlighted the extreme concentration of the tech industry. With only a handful of companies controlling the underlying infrastructure of the internet, a single error in one corner of the ecosystem can trigger a global recessionary event. Analysts are now calling for greater diversification in the enterprise tech stack. The reliance on a ‘monoculture’ of Windows and specific security agents is being scrutinized by regulators who are concerned about the systemic risk posed by dominant tech players. This event may well be the catalyst for new antitrust or resilience regulations designed to prevent such a totalizing collapse in the future.
Geopolitical Ramifications and National Security Concerns
From a geopolitical perspective, the outage raised immediate questions about national security and the vulnerability of digital borders. While it was quickly determined that this was not a state-sponsored attack, the fact that a single software update could disable the digital infrastructure of several G20 nations is a cause for alarm. Defense ministries and intelligence agencies were forced to revert to secure, secondary communication lines to ensure that national security was not compromised during the hours of peak instability. The Hindu reported that several Indian ministries held emergency meetings to assess the impact on the nation’s digital sovereignty.
This event serves as a stark reminder that the digital infrastructure of a nation is as critical as its physical borders, power grids, or water supply. The ease with which the system was brought down suggests that in a potential future conflict, ‘cyber-neutralization’ could be achieved with minimal effort if an adversary were to exploit similar vulnerabilities in the software supply chain. Governments are now likely to demand greater transparency from software vendors regarding their update protocols and to mandate ‘kill switches’ or rollback mechanisms that can be triggered without requiring physical access to the hardware.
Conclusion: Navigating the Future of Digital Resilience
The 2024 Microsoft outage will be remembered as a turning point in the history of the internet. It has exposed the fragile foundations upon which our digital society is built and forced a reckoning with the risks of extreme centralization. Microsoft’s decision to extend mail timeouts to 48 hours was a necessary tactical response, but it does not address the underlying strategic vulnerability of the global tech stack. Moving forward, the focus must shift from pure efficiency to ‘resilient redundancy.’ This means investing in diverse operating environments, prioritizing offline capabilities for essential services, and demanding more rigorous testing standards for software updates that interact with the system kernel.
Ultimately, the recovery from this outage will take days, if not weeks, as the digital backlog is cleared and trust is slowly rebuilt. For businesses and governments alike, the lesson is clear: the convenience of the cloud must never come at the cost of total systemic dependence. As we move toward an even more interconnected future with the integration of AI and IoT, the safeguards we put in place today will determine our ability to weather the next inevitable digital storm. The Hindu’s comprehensive coverage of this event serves as a roadmap for understanding the complex intersections of technology, law, and global commerce in an age of digital fragility.
Leave a Reply